
Production Performance: Scale Private Models with AI Infrastructure Engineering
Stop relying on rate-limited, expensive public API endpoints. We deliver end-to-end AI infrastructure engineering, targeted LLM fine-tuning services, and enterprise-grade custom model deployment. Own your weights, enforce zero-data-retention compliance, and achieve sub-millisecond inference speeds with custom GPU cluster optimization.
The Reality of Public SaaS APIs vs Self-Hosted Infrastructure
Renting API tokens from third-party model providers creates unpredictable cost spikes, latency bottlenecks, and major data privacy risks. Modern AI infrastructure engineering enables private LLM hosting leveraging vLLM inference serving and model quantization—giving enterprises full model ownership and predictable operational costs.
| Feature / Dimension | Renting Public API Tokens (OpenAI / Anthropic) | Self-Hosted Hajana LLM Infrastructure |
|---|---|---|
| Cost Predictability | Unpredictable Expenses: Bill scales linearly with token volume; sudden cost spikes during high traffic | Fixed GPU Compute Costs: Predictable monthly cloud or on-prem infrastructure footprint |
| Data Privacy & Sovereign Boundaries | Data Privacy & Compliance Risks: Sensitive corporate data sent across third-party networks | Zero Data Retention Compliance: Complete data sovereignty inside VPC boundaries (AWS, GCP, Azure, On-Prem) |
| Availability & Throughput SLAs | Rate Limits & Downtime: Subject to third-party outages, rate throttling, and API changes | Dedicated High Availability: Auto-scaling Kubernetes (K8s) GPU clusters with 99.99% uptime SLAs |
| Model Weights & Customization | Generic Model Output: Unable to alter base weights for specialized domain tasks | Custom Fine-Tuned Weights: Tailored LoRA/QLoRA domain adapters tuned specifically to company data |
Unpredictable Expenses: Bill scales linearly with token volume; sudden cost spikes during high traffic
Fixed GPU Compute Costs: Predictable monthly cloud or on-prem infrastructure footprint
Data Privacy & Compliance Risks: Sensitive corporate data sent across third-party networks
Zero Data Retention Compliance: Complete data sovereignty inside VPC boundaries (AWS, GCP, Azure, On-Prem)
Rate Limits & Downtime: Subject to third-party outages, rate throttling, and API changes
Dedicated High Availability: Auto-scaling Kubernetes (K8s) GPU clusters with 99.99% uptime SLAs
Generic Model Output: Unable to alter base weights for specialized domain tasks
Custom Fine-Tuned Weights: Tailored LoRA/QLoRA domain adapters tuned specifically to company data
Our 4-Stage LLM Infrastructure & Tuning Pipeline
A rigorous engineering framework to train, optimize, deploy, and monitor custom enterprise models.
Stage 1: Data Curation & Dataset Engineering
Filter, clean, and format domain-specific datasets into high-quality instruction-tuning JSONL pairs for targeted fine-tuning.
Outcome
High-Quality Instruction-Tuning Datasets
Stage 2: Fine-Tuning & Parameter Efficient Training
Execute domain adaptation via QLoRA, DeepSpeed, and FlashAttention to tune open models (Llama 3, Mistral, Qwen) on private compute clusters.
Outcome
Domain Adaptation via QLoRA & DeepSpeed
Stage 3: Quantization & Inference Optimization
Apply AWQ/GGUF quantization techniques and set up high-throughput serving architectures using vLLM or TensorRT-LLM.
Outcome
AWQ/GGUF Quantization & High-Throughput Serving
Stage 4: Production LLMOps & Monitoring
Deploy continuous LLMOps pipelines featuring model drift detection, automated fallback routing, latency tracing, and live cost analytics.
Outcome
Continuous LLMOps Telemetry & Automated Fallbacks
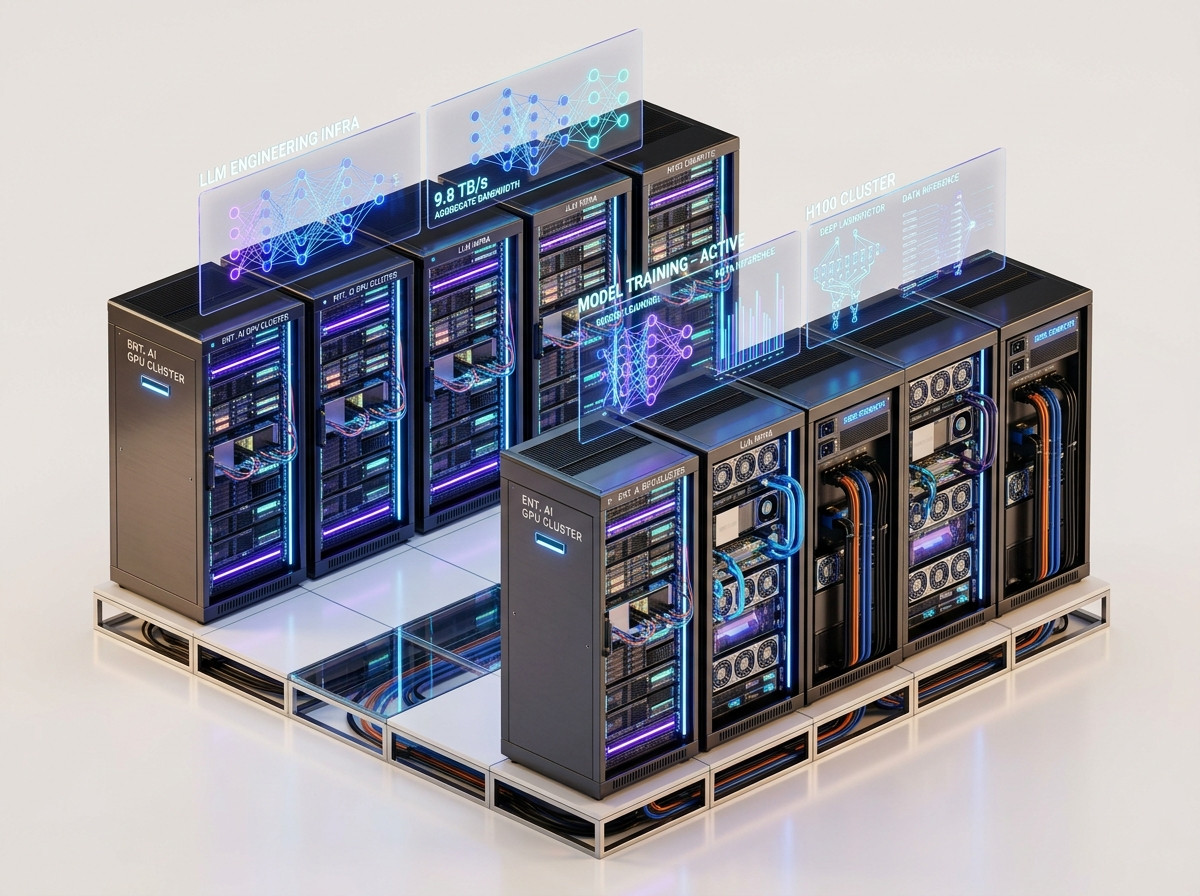
Core Solutions within Our LLM Engineering Suite
High-performance infrastructure components built for production AI scale.
From private on-premise GPU hosting to sub-millisecond quantized model serving, our engineers build dedicated infrastructure that ensures 100% data sovereignty and predictable compute budgets.

Enterprise LLM Fine-Tuning Services
Custom LLM fine-tuning services to train specialized base models on proprietary domain data, codebases, or industry jargon with total accuracy.

Private LLM Hosting & VPC Isolation
Deploy air-gapped private LLM hosting on dedicated AWS EC2 (P5/G5 instances), GCP Cloud GPUs, or bare-metal NVIDIA clusters.

High-Throughput Inference Engines
Configure vLLM, SGLang, and TensorRT-LLM for continuous batching, prefix caching, and ultra-low latency inference response times.

Model Quantization & Compression
Compress 70B+ parameter models down to 4-bit or 8-bit precision via AWQ and GPTQ to slash GPU RAM requirements without accuracy loss.

Intelligent Multi-Model Router
Engineer low-latency gateway routers that classify query intent, routing routine requests to fast 8B models and complex prompts to larger base models.

Enterprise LLMOps & Continuous Evaluation
Set up automated benchmark pipelines (Ragas, DeepEval) to continuously score output quality, safety guardrails, and latency metrics.
Strategic Value for Engineering & Executive Leadership
Transforming AI from a high-cost operational variable into scalable asset ownership.
For Chief Technology Officers (CTOs)
Take control of base model weights, eliminate external API vendor lock-in, and build long-term intellectual property through AI infrastructure engineering.
For Chief Information Security Officers (CISOs)
Ensure strict data protection aligned with major security frameworks (HIPAA, SOC 2, FedRAMP) by processing all AI inference within isolated private clouds without third-party data leaks.
For VPs of Infrastructure / DevOps Leads
Standardize model deployment with Kubernetes operators, automated GPU auto-scaling, and robust Prometheus/Grafana observability dashboards.


Schedule Your Infrastructure & LLM Tuning Review
Consult directly with our senior infrastructure architects to evaluate your token workloads, design custom GPU serving stacks, and plan seamless custom model deployment with high-throughput AI infrastructure engineering.