
Unified Insight: Transform Siloed Data into Enterprise Knowledge Intelligence
Unlock company knowledge trapped across PDFs, SharePoint, Slack, and legacy databases. We deliver production-grade RAG system engineering and enterprise vector search architectures that allow your organization to query its entire knowledge base with instant, sub-second accuracy through semantic enterprise search.
Why Naive RAG Fails Enterprise Accuracy Standards
Simple vector search and generic RAG scripts fail when applied to complex corporate data. Enterprise-grade enterprise knowledge intelligence integrates knowledge graph AI with advanced graph RAG architecture to guarantee reliable contextual information retrieval without hallucinations or security leaks.
| Feature / Dimension | Naive Vector Search & Vanilla RAG | Hajana Enterprise Knowledge Intelligence |
|---|---|---|
| Document Context & Hierarchy | Context Blindness: Splits text arbitrarily, breaking parent-child relationships and tabular metadata | Graph RAG Architecture: Maps entities, relationships, and document hierarchies into structured knowledge graphs |
| Permissions & Security | Security Blind Spots: Ignores document-level Access Control Lists (ACLs), risking data breaches | Role-Based Security: Strict RBAC and ABAC filtering embedded directly inside the vector retriever |
| Retrieval Accuracy | High Hallucination Rate: Retrieves loosely related text chunks without verifying factual accuracy | Hybrid Retrieval & Reranking: Combines BM25 keyword matching, vector similarity, and neural rerankers |
| Data Freshness | Stale Data Stores: Requires manual re-indexing when documents are modified or archived | Real-Time Data Pipelines: Continuous streaming ingestion synchronizes source changes instantly |
Context Blindness: Splits text arbitrarily, breaking parent-child relationships and tabular metadata
Graph RAG Architecture: Maps entities, relationships, and document hierarchies into structured knowledge graphs
Security Blind Spots: Ignores document-level Access Control Lists (ACLs), risking data breaches
Role-Based Security: Strict RBAC and ABAC filtering embedded directly inside the vector retriever
High Hallucination Rate: Retrieves loosely related text chunks without verifying factual accuracy
Hybrid Retrieval & Reranking: Combines BM25 keyword matching, vector similarity, and neural rerankers
Stale Data Stores: Requires manual re-indexing when documents are modified or archived
Real-Time Data Pipelines: Continuous streaming ingestion synchronizes source changes instantly
Our 4-Stage Knowledge Engineering Architecture
A secure engineering approach for transforming raw company files into queryable enterprise context.
Stage 1: Multi-Modal Data Ingestion
Execute automated unstructured data ingestion across Confluence, Notion, Google Drive, SQL databases, and internal API endpoints.
Outcome
Automated Multi-Modal Source Ingestion
Stage 2: Knowledge Graph Building & Chunking
Apply semantic chunking strategies while mapping relationships, schemas, and metadata into graph databases for hybrid search retrieval.
Outcome
Semantic Chunking & Knowledge Graph Mapping
Stage 3: Neural Retrieval & Reranking
Deploy dense retrieval algorithms backed by cross-encoder neural rerankers as part of custom RAG system engineering pipelines.
Outcome
Cross-Encoder Neural Reranking & Hybrid Search
Stage 4: Enterprise RBAC & LLM Synthesis
Pass context through security filters before synthesizing clear, verifiable answers backed by exact source document citations.
Outcome
Strict RBAC Filtering & Grounded Source Citations
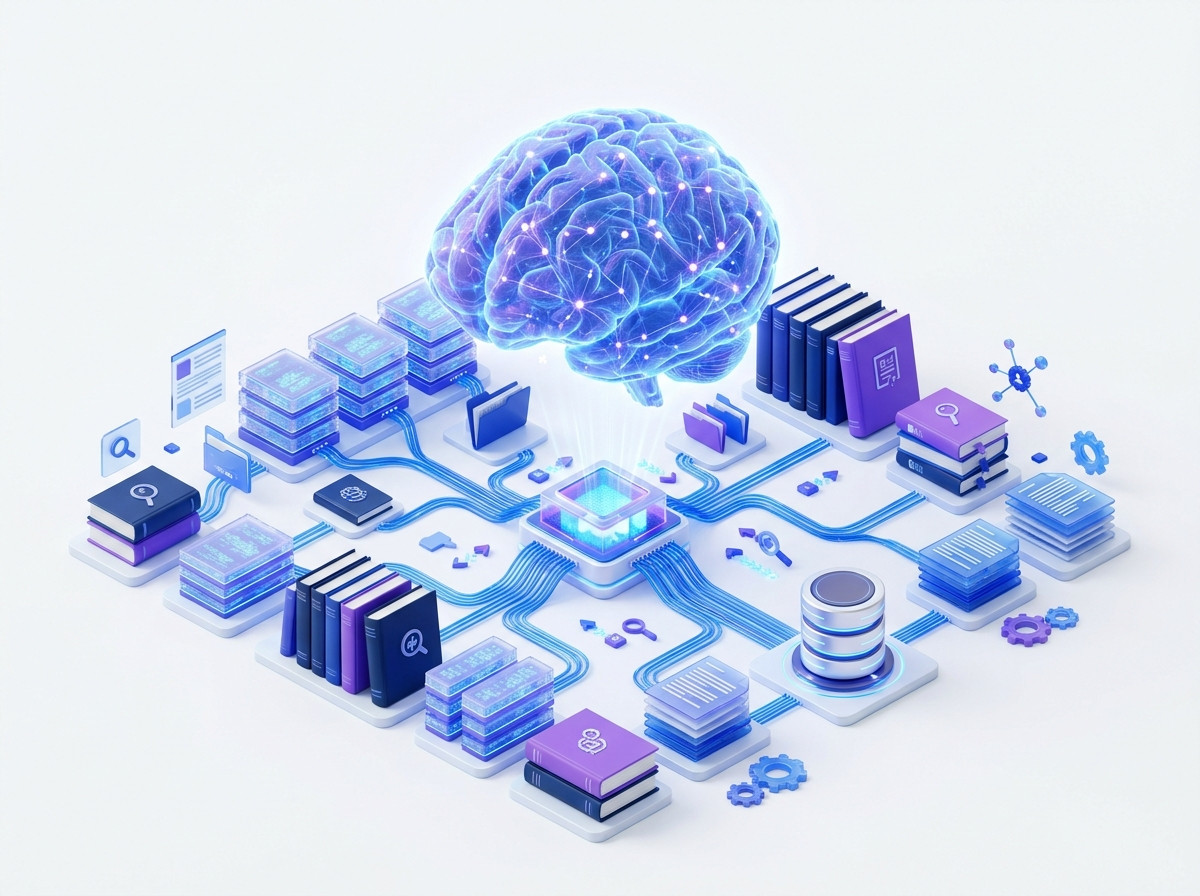
Core Modules in Our Knowledge Intelligence Suite
Enterprise-grade components designed for secure semantic retrieval across deep data lakes.
We unite vector search indexes, knowledge graph relationships, and role-based access controls to create an immutable, cited knowledge layer that eliminates shadow AI and powers trusted decisions.

Enterprise Vector Search & Indexing
Deploy high-performance vector stores (Pinecone, Qdrant, Milvus) optimized for fast enterprise vector search over millions of multi-modal assets.

Knowledge Graph AI Integration
Combine relational entity mapping with LLMs using knowledge graph AI to answer complex multi-hop queries across departments.

Document ACL & Governance Synchronization
Inherit permissions from source systems (Active Directory, Okta, OAuth) so users only query files they are authorized to access.

Technical Spec & Policy Engine
Give engineering and compliance teams instant, cited access to standard operating procedures, legal code, and internal engineering documentation.

Multi-Modal Chart & Table Parsing
Extract, interpret, and query structured financial data, diagrams, and tables embedded within complex PDF reports.

Automated Knowledge Drift Detection
Continuously evaluate vector index quality, detect outdated documentation, and alert knowledge managers to conflicting policies.
Enterprise Value Across Leadership
Enabling instant data access and informed decision-making across executive functions.
For Chief Information Officers (CIOs)
Eliminate shadow AI usage by deploying centralized enterprise knowledge intelligence tools built with SOC 2-aligned security controls and enterprise access integration.
For Chief Technology Officers (CTOs)
Reduce developer onboarding times and developer lookup overhead by providing natural language access to internal codebases and architecture designs.
For Legal & Compliance Directors
Accelerate contract discovery and policy auditing with deterministic source citation and traceable data provenance.


Build Your Enterprise Knowledge Base
Consult directly with our AI architects to evaluate your organization's data layout, quantify search friction, and engineer custom enterprise knowledge intelligence solutions through advanced RAG system engineering.